AI Agents Put Data Observability at the Center of Enterprise Architecture
- Cargo
- Machine Learning
- Shipped
- Shipper
- Jonathan Anthony
- Readers
- 681
Agents need direct, runtime access to data and create temporary databases, making traceability and governance core design requirements.
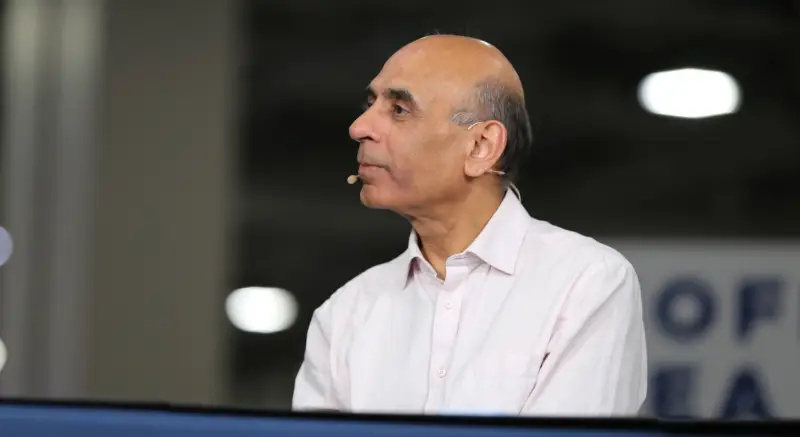
AI agents are changing a basic assumption behind enterprise data systems: that information can be prepared in advance, passed through a pipeline and consumed later. Agents may need to query live databases, assemble task specific context and create temporary stores while they work. That shift puts observability and traceability inside the data architecture, where teams need them to understand what an agent accessed and how it reached an action.
That is the argument Sanjeev Mohan, principal at data and AI advisory firm SanjMo and author of Designing the AI-Driven Data Foundations, made at KubeCon + CloudNativeCon NA 2026. The event added a dedicated track for AI inference and agents, reflecting the growing role of AI workloads in cloud native systems. Mohan’s point is that the infrastructure conversation can’t stop at models: production performance also depends on the quality, accessibility and visibility of the underlying data.
“AI can only be successful if it’s built on a solid foundation,” Mohan said. “You have no observability or transparency into it. No matter what you do on top of it, it will not be successful.”
Agents challenge pipeline assumptions
Traditional data workflows were built around information created in operational systems, then extracted, transformed, cataloged and prepared for later use. That approach can serve human users who consume reports on a schedule. It becomes harder to rely on when software agents need information during an active task. Mohan says agents may seek direct database access instead of waiting for a prepared pipeline to finish.
“They’re not going to wait for this pipeline to finish. They want access to the database directly,” he said. He has also described thousands of agents as a scale that changes the demands on data infrastructure. The practical issue is not simply query speed. If agents can read from many sources at runtime, teams need a way to see which sources were used, what data was available and how that information shaped the resulting action.
Mohan also describes agents creating short lived databases, copying data and trying different reasoning paths before choosing what to do. That behavior adds complexity to data lineage: the information that matters may be assembled temporarily for a particular task rather than stored in one durable, centrally prepared dataset. A system that records only the final output may leave teams without enough context to reconstruct the process behind it.
Governance has to follow the runtime context
Mohan illustrated the audit challenge with an agent reviewing a loan application. It might consult census records and social media before recommending a decision. The key question is how an organization can later establish what the agent consulted and how those inputs affected its result.
“Governance becomes really important, and this is not like governance in the past where you would govern your data and then have a deterministic CFO report dashboard run on it,” Mohan said.
That distinction matters for system design. A dashboard usually presents a result produced from known data and a repeatable process. An agent may gather different material for each task and build its working context as it runs. Teams therefore need visibility into both stored data and the activity that connects data to an action. Observability can help make that activity inspectable, while governance needs to account for how information is selected and used at runtime.
The interview does not lay out a particular technical standard or implementation for capturing this history. It does point to a concrete design requirement: data platforms serving agents need to preserve enough state and context to support later review. Without that record, teams may see what an agent did without being able to explain the path that led there.
Platforms may need to combine data types
Mohan expects future platforms to bring structured and unstructured information together in a converged system. His reasoning follows from the changing role of context. Agents may need tables, documents and other information sources to perform a task, and the useful combination can vary from one run to another.
“You have to save the state and you have to build the context, and this context is being built in runtime,” he said. “The context for the same task could be very different for the three of us. So we’ll see new kinds of databases.”
That points to a broader architectural question: how should a data system represent context that is assembled temporarily and differs across users or tasks? Mohan’s remarks make the need clear, though they don’t specify what those new databases will look like or how organizations should migrate to them. For teams building agent systems, a useful next step is to examine whether existing data infrastructure can expose access and preserve task context across the full path from query to action.
Mohan discussed these issues with theCUBE Research’s John Furrier and Rebecca Knight during an interview at KubeCon + CloudNativeCon NA. His book, published in June 2026 by John Wiley & Sons Inc., examines how treating agents as first class data consumers changes architectural assumptions. The immediate takeaway for platform teams is straightforward: if agents build their working context at runtime, observability and governance have to reach that runtime too.


