Google’s Gemini Decisions API Prices Narrow AI Answers at $0.10 per Million Input Tokens
- Cargo
- Machine Learning
- Shipped
- Shipper
- Maria Deutscher
- Readers
- 547
Gemini Decision 1 returns short, confidence-scored answers to three question types, with multimodal input support and a reported 50–100 ms median model compute time.
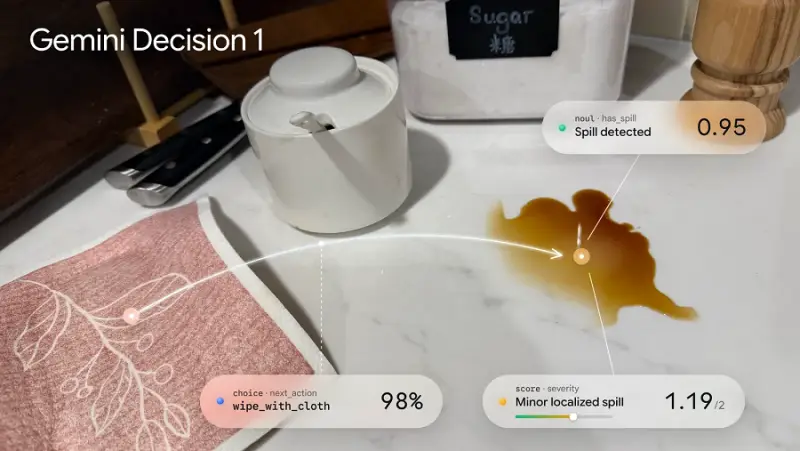
Google’s Gemini Decisions API is built for applications that need a judgment they can consume directly, rather than a paragraph that must be interpreted and checked. Its Gemini Decision 1 model handles three kinds of requests—yes-or-no questions, multiple-choice questions, and ratings on a user-defined scale—and returns concise answers with a confidence score. Google prices input at 10 cents per million tokens and does not charge for output tokens.
That narrow scope is the product’s central trade-off. General-purpose large language models can respond to a wide range of prompts, but an application using them may need to parse their prose, remove irrelevant detail, and check whether the response fits the expected format. A decision model limits the task and produces a simpler result for downstream software to handle. The approach is most relevant when a product needs a repeatable classification or selection, rather than an open-ended explanation.
Three response types, multimodal input
Gemini Decision 1 can return a yes or no, choose among options, or assign a value on a scale specified by the user. For instance, a cybersecurity team could ask it to rate the severity of an antivirus alert from 1 to 10. That example illustrates the model’s intended role: converting supplied material into a bounded answer an application can route or display.
A request contains both the question and the material the model should assess. Google says that material can total up to 256,000 tokens and include text, audio, images, video, or a combination of those formats. This gives developers a way to ask a constrained question about varied inputs. The stated 256,000-token limit describes the supported dataset size; it should not be confused with the separate context limit cited in Google’s latency claim.
The output includes a confidence score alongside the short answer. Applications can use that score when deciding whether to act on a result or send it for another check. It offers a signal for handling uncertainty, but the source material does not describe a universal threshold or guarantee that a given confidence value corresponds to a particular accuracy rate. Teams would need to assess how the score behaves for their own data and tasks.
Latency and cost claims
Google says Gemini Decision 1 scores options without token-by-token decoding, the process commonly used to generate text one token at a time. In a blog post, Google DeepMind product manager Min Choi and principal scientist Felix Yu report median model compute latency of 50–100 milliseconds and end-to-end latency of 150–250 milliseconds. They say the figures apply across multimodal inputs and contexts up to 16,000 tokens, with latency remaining nearly flat from one to 100 questions per request.
Those figures describe the performance Google reports; they are not a promise that every deployment will see the same response time. The distinction between model compute and end-to-end latency also matters in practice: the latter includes time beyond the model’s own computation. The reported near-flat latency as question counts rise may interest systems that evaluate several questions against a shared request, though the published figures alone do not establish performance for every workload.
At 10 cents per million input tokens, with no charge for output tokens, the API’s pricing is geared toward high volumes of compact decisions. Google says the model costs nearly five times less than its entry-level Gemini 3.5 Flash-Lite language model. That comparison is Google’s, and actual costs will depend on how much input an application sends and how often it calls the service. Gemini Decision 1 is also available through a limited free tier in Google AI Studio.
How it compares with other decision models
Decision models are optimized for a restricted set of responses, which can make them faster for those tasks and easier to integrate into software than a model that writes free-form text. The benefit comes with a boundary: questions outside the supported formats are not part of the stated use case. Developers must also decide how to handle uncertain answers and whether a short result contains enough information for a particular workflow.
Google compared Gemini Decision 1 with Jev, a decision model from TypeSafe AI, and OpenAI’s Decisions API. Google says its model performed better on seven of the nine benchmarks in its evaluation, while Jev was slightly more cost-efficient. The available account does not provide the benchmark names, scores, test setup, or pricing details behind that comparison, so it supports a limited conclusion: Google reports an advantage on most of its selected tests, alongside a cost edge for Jev.
Jev launched in mid-September and gained one million users within a few days, according to the source material. Three weeks later, TypeSafe raised $870 million at a $7.5 billion valuation. Those figures show the attention the category attracted, but they do not establish the models’ technical quality or the size of the market for narrow answer systems.
For developers, the practical question is whether a task can be expressed as one of the three supported response types and whether a compact answer is sufficient for the product. The API’s price and latency claims make that evaluation worthwhile for repeated classification and scoring tasks. The next useful evidence will be results on named benchmarks, details of the evaluation methods, and performance on the specific inputs and error cases teams encounter in deployment.


