Edelbyte Raises $70 Million to Build AI Oriented Data Analytics Platform
- Cargo
- Machine Learning
- Shipped
- Shipper
- Maria Deutscher
- Readers
- 879
The Tel Aviv startup combines data storage, vector search and analytics, with query federation and indexing aimed at petabyte scale workloads.
Edelbyte is building a data platform around a practical challenge for companies deploying AI agents: business data is spread across systems, while search and analysis workloads increasingly need to work across different data types. The Tel Aviv startup says its platform can keep conventional records and AI related vectors together, run several kinds of queries, and reach multipetabyte datasets with latency below 100 milliseconds.
The company launched with $70 million raised across two rounds. Sequoia and Quiet Capital led the investments, with Greenoaks and Swish Ventures also contributing. CTech reported a $500 million valuation. Edelbyte plans to use the proceeds to expand its customer base and hire employees.
A data platform for several workloads
Edelbyte presents its product as an alternative to Snowflake and Databricks. The platform is designed to store up to hundreds of petabytes of data in a deployment and support more than one way of working with that information. Its intended users can run searches, business intelligence calculations and graph processing through the same system.
That range matters because these tasks ask different questions of data. Search can retrieve records that match a user’s request. Business intelligence tools calculate measures across records. Graph processing examines relationships between data points, such as connections created when information comes from the same system. Edelbyte’s pitch is that a common platform can support these uses without forcing every workload into a single query pattern.
The system also stores vectors alongside conventional records. Vectors are mathematical representations that can encode features of items, helping software identify related content. A product listing, for example, can be stored with a representation that makes it easier to retrieve similar listings. For AI agents that need to find relevant information as they work, this kind of similarity search can complement searches based on exact fields or terms.
Combining these capabilities creates a demanding engineering problem: different workloads need different ways to organize and retrieve information, and large deployments can span multiple storage systems. Edelbyte says its design addresses that problem through query federation and automated index customization. Those are the mechanisms behind its performance claims, though the company has not provided benchmark methodology or comparative results in the available details.
Queries run where data already lives
Many analytics workflows move information into a dedicated processing environment before running queries. That transfer takes time and consumes network bandwidth, especially when datasets are large. Edelbyte uses query federation to run queries in the systems where the data is already stored, rather than requiring customers to load all of it into Edelbyte first.
The approach could reduce the time and transfer costs associated with moving data between environments. It also means that performance depends in part on the systems holding the data and the connections between them. The company’s stated latency of under 100 milliseconds for multipetabyte datasets is therefore a claim to assess in the context of workload, deployment and measurement details. Those details aren’t specified here.
Edelbyte also generates indexes to speed up retrieval. An index is an auxiliary structure that helps a system locate relevant data without scanning everything. Its usefulness depends on how an application accesses the data: an index tuned for one pattern may not help a different query. The company says its platform automates some of the manual work involved in tailoring indexes to access patterns.
Automation could ease a recurring operational burden for teams managing many applications and changing query needs. It also raises questions prospective users will want answered: how the system identifies useful patterns, how quickly indexes adapt when workloads change, and what compute or storage overhead they add. Edelbyte has not supplied those details in the information available.
Founders bring experience with real time data
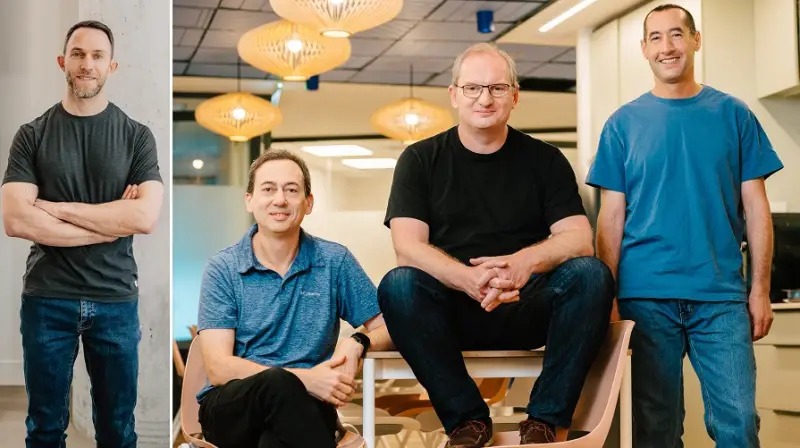
Edelbyte was founded last year by Avner Aharoni, Evgeney Ryzhyk, Alexander Sloutsky and Yoni Leibowitz, all former Microsoft executives. They helped develop Azure Data Explorer, a service for analyzing real time information streams that customers often call Kusto, after its query language. That background connects the founders to large scale analytics and gives context for Edelbyte’s focus on query performance.
Chief Executive Aharoni said companies’ search and analytics systems were built before AI became central to business operations. He expects the volume and complexity of queries to grow beyond what older infrastructure was designed to handle. Edelbyte’s product reflects that view by bringing together data retrieval, analysis and vector support.
The company says several Fortune 500 customers already use its platform in petabyte scale data environments. That is an early sign of enterprise use, but it doesn’t disclose customer names, deployment counts or independently measured performance. Those omissions make it difficult to compare the platform with established analytics products on cost, reliability or speed.
The next useful evidence will be more detail on production workloads: how federation performs across different storage systems, how index automation behaves as access patterns shift, and what it costs to operate at scale. For now, Edelbyte’s defining bet is that organizations will want one platform to query data in place while supporting both conventional analytics and AI agent retrieval.


