NVIDIA’s Memory Hierarchy Aims to Raise AI Inference Throughput per Dollar
- Cargo
- Machine Learning
- Shipped
- Shipper
- Amr Elmeleegy
- Readers
- 718
NVIDIA combines lower precision, cache offload and storage tiers to ease HBM pressure, reporting up to 30× more AgentX throughput per dollar.
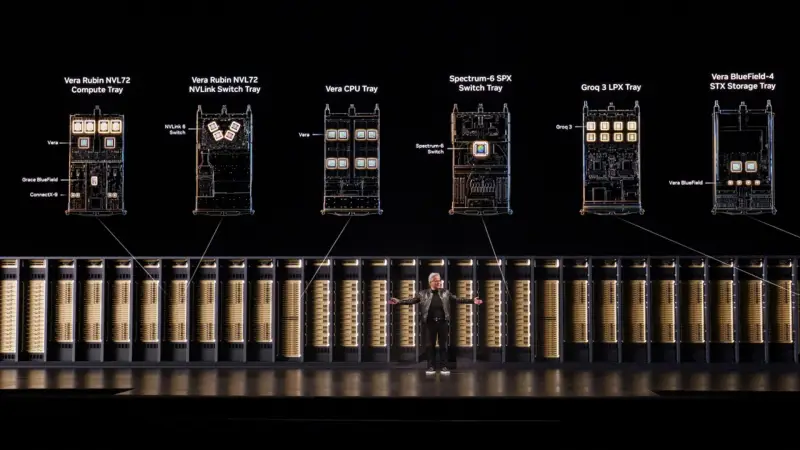
AI inference is running into a memory problem that adding more high-bandwidth memory (HBM) can’t solve on its own. NVIDIA’s approach combines lower precision, memory placement and software that moves inactive data to cheaper tiers. The company says this full-stack design raised agentic throughput per dollar by up to 30× between its GB300 NVL72 and Vera Rubin NVL72 platforms, while HBM capacity per GPU grew by about 3%.
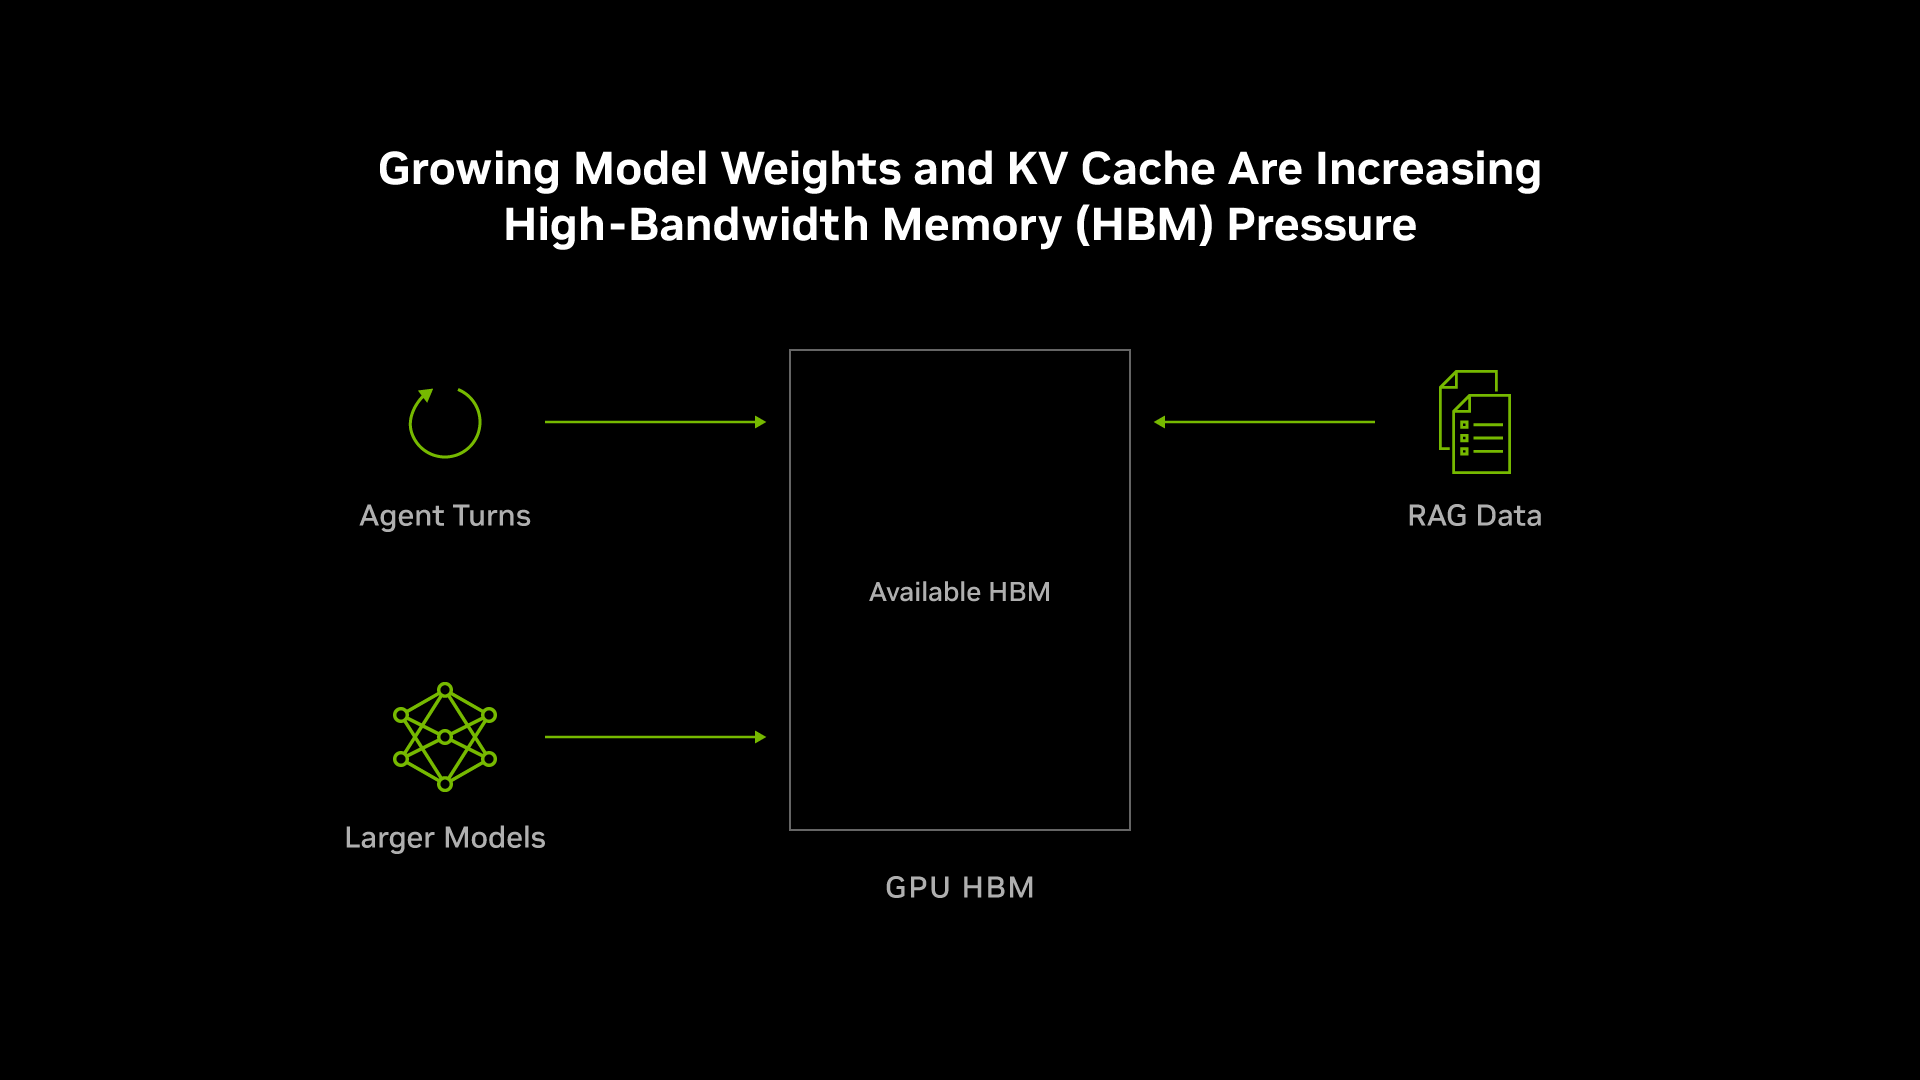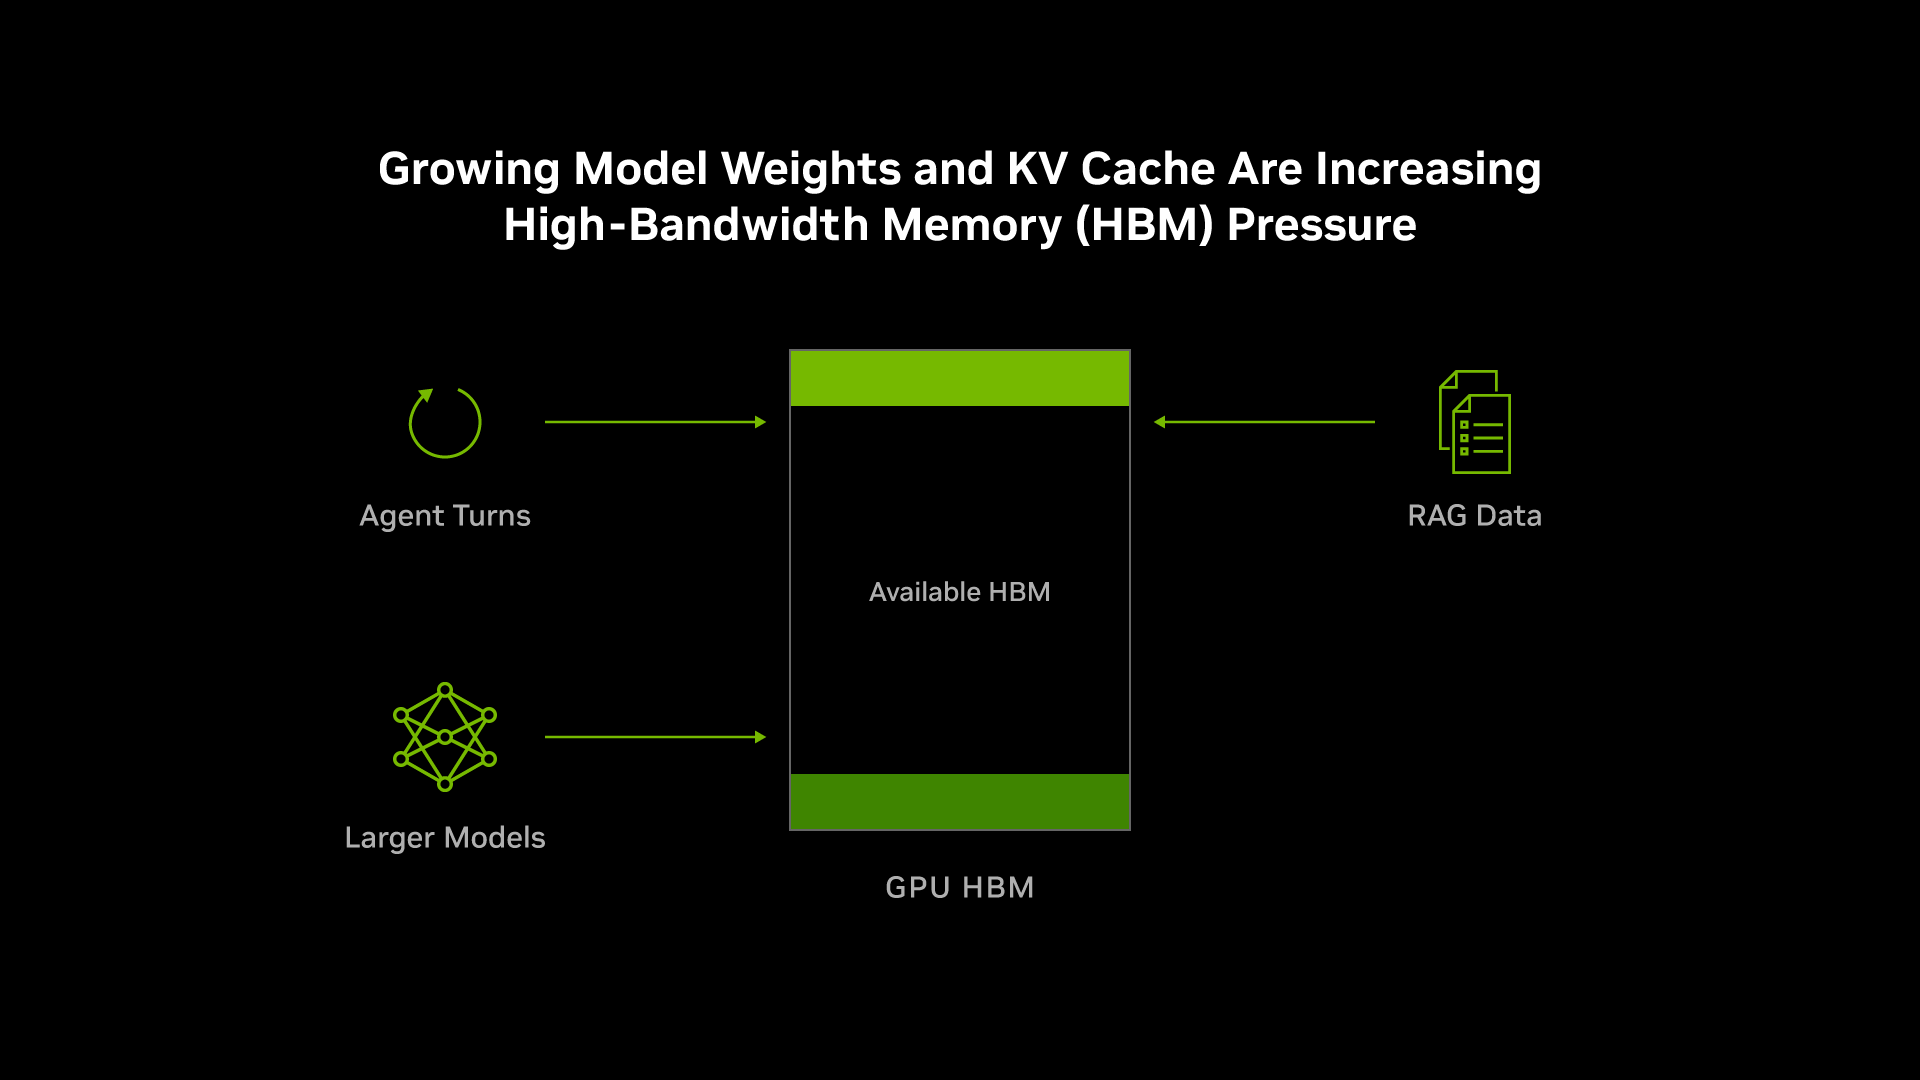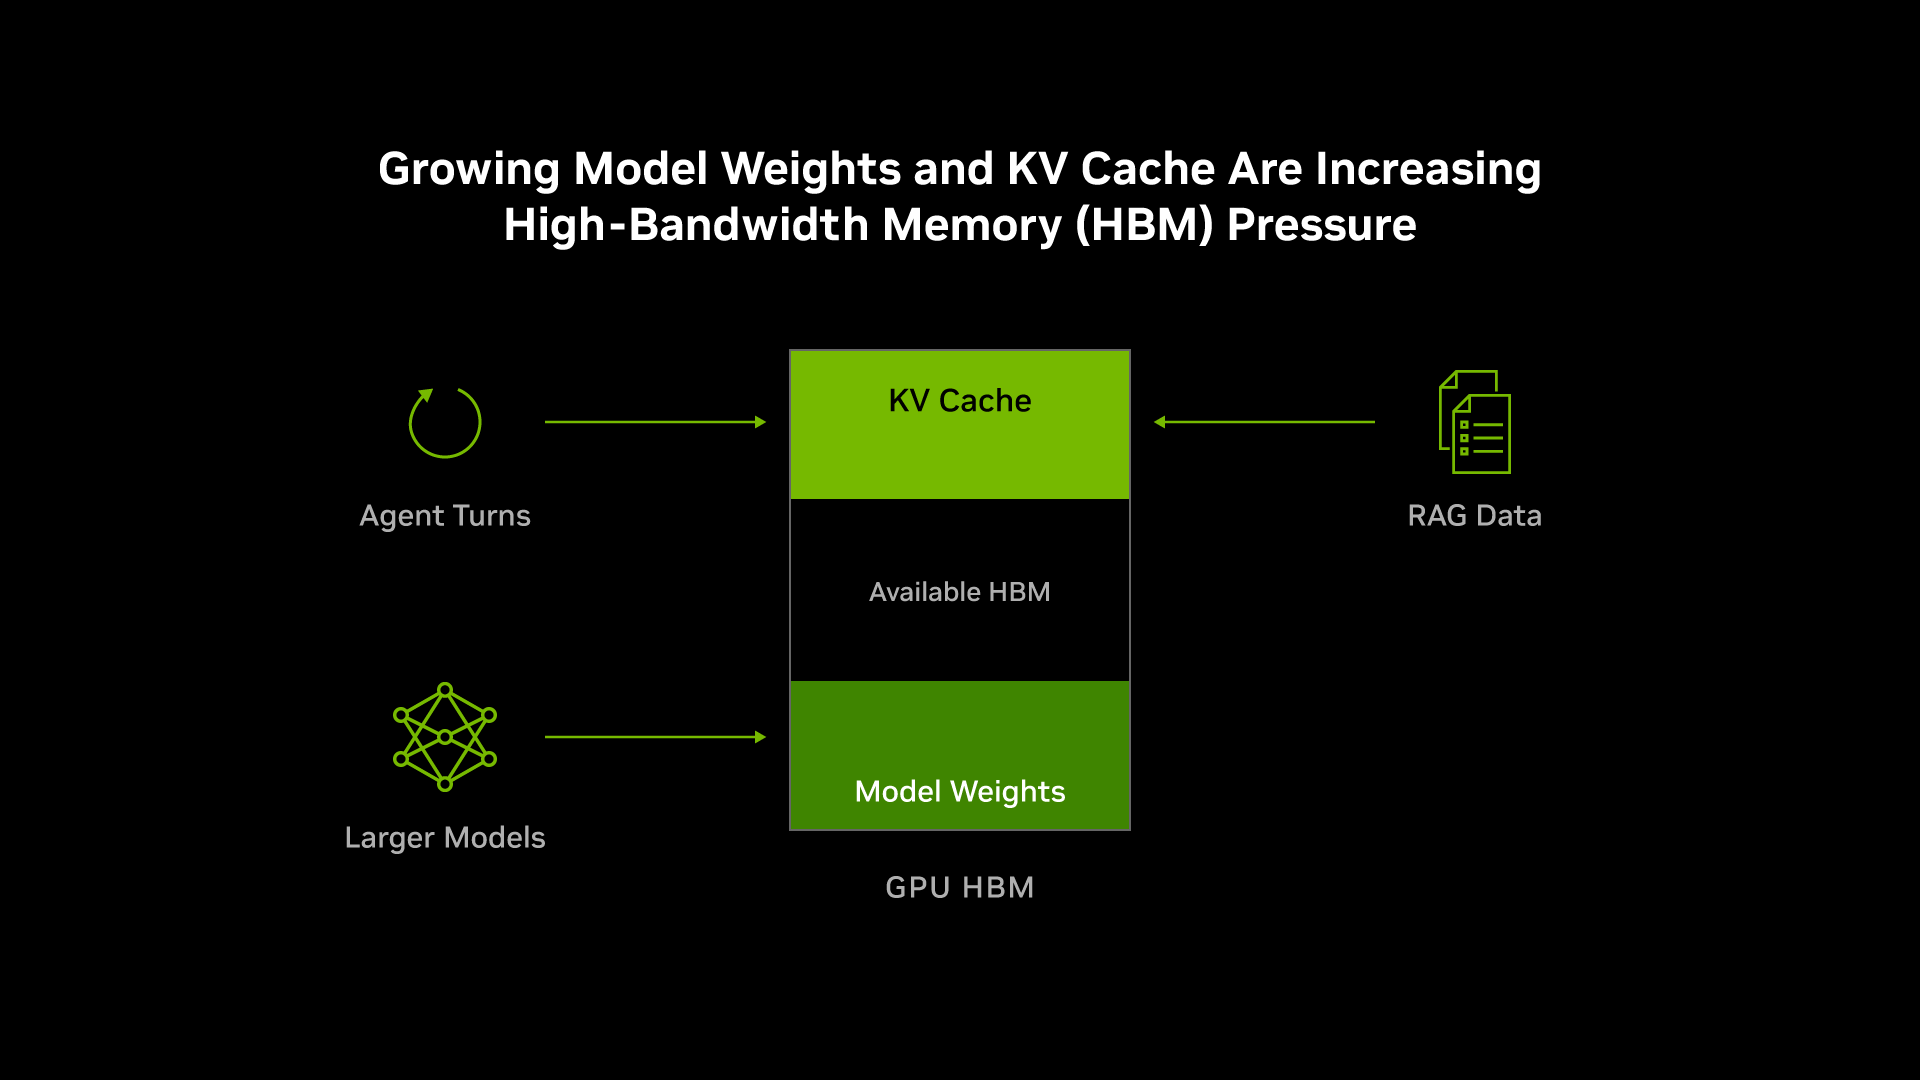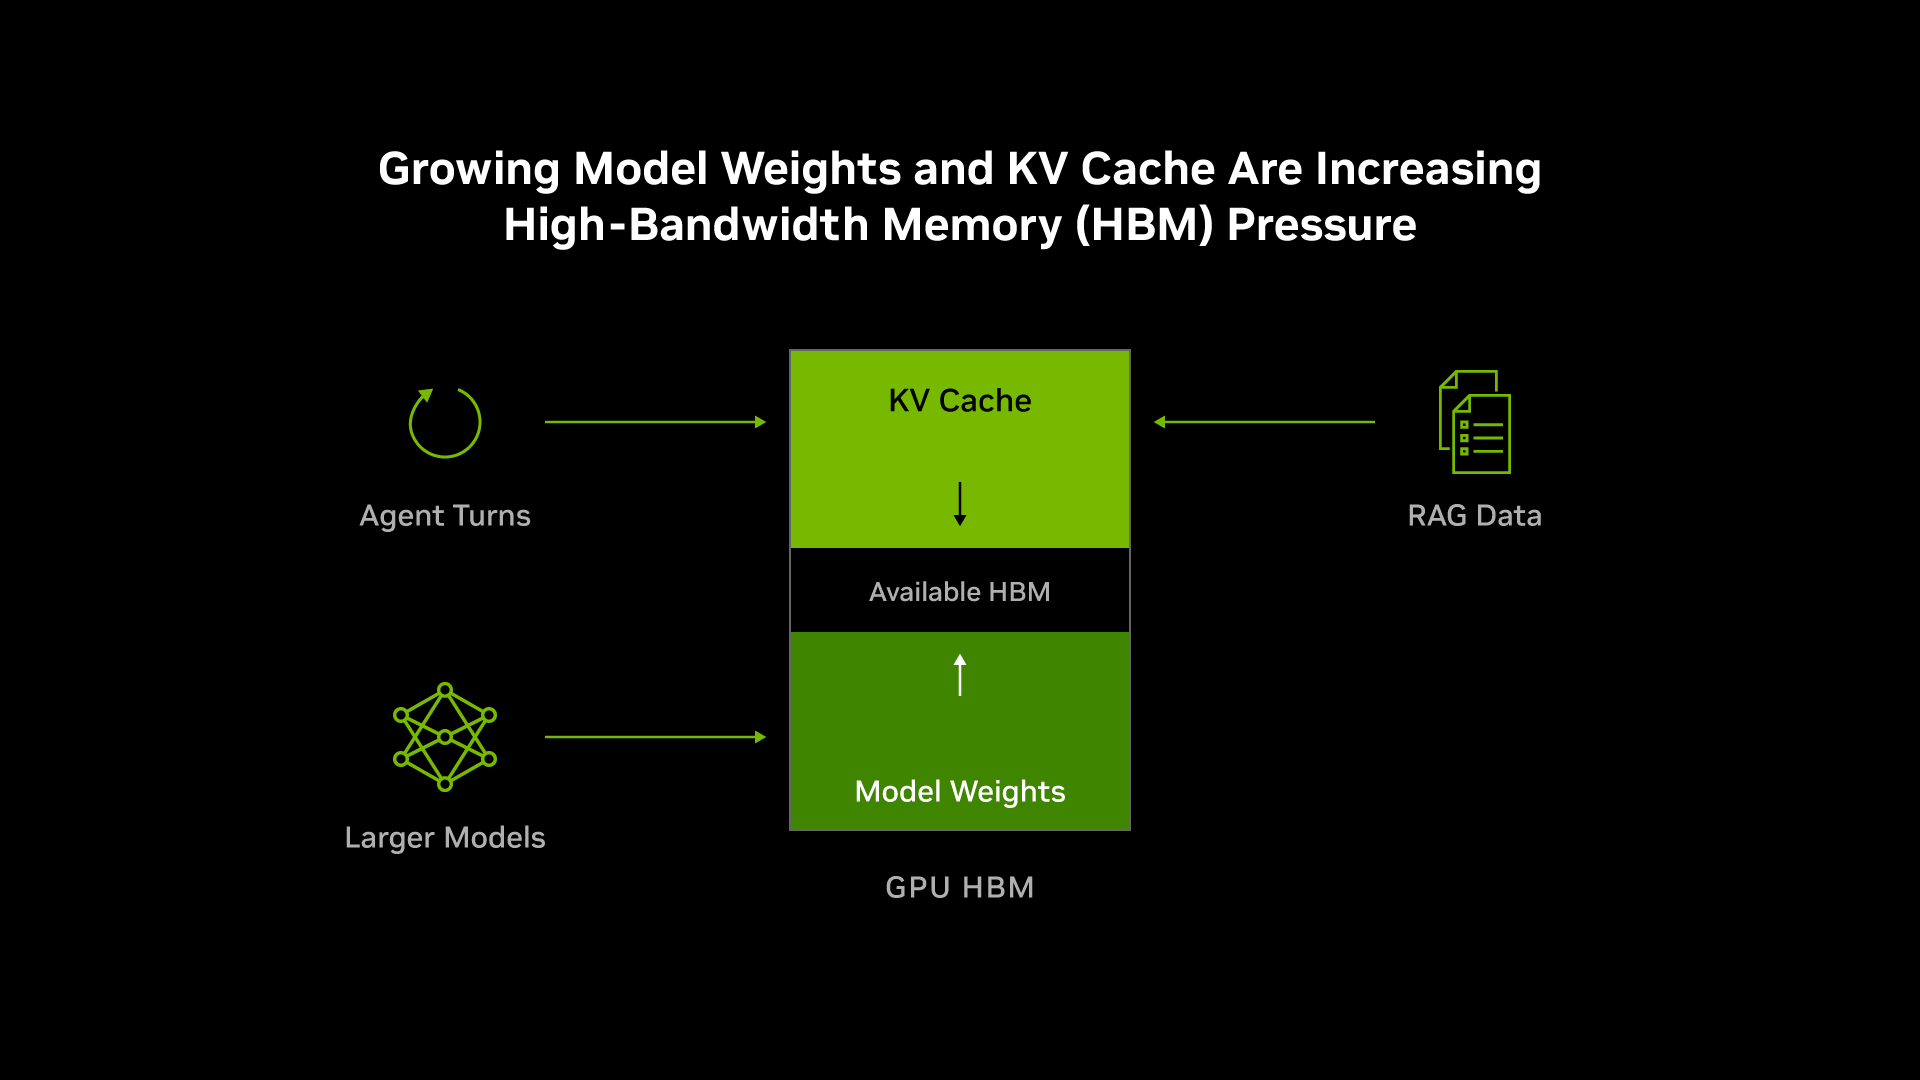
That result depends on treating memory as a hierarchy. HBM is fast and close to the GPU, but expensive and limited. CPU memory, local solid-state drives and shared storage offer more capacity at lower cost per bit, with slower access. The practical goal is to keep active data close to compute, compress what must stay there, and retrieve other data before it is needed.
Why agentic inference strains HBM
Inference workloads compete for HBM space. Model weights occupy memory throughout a run, while the key-value (KV) cache stores context for active requests so the model doesn’t have to process the same information again. As models grow and applications make repeated calls to tools, both demands rise.
Agentic requests can carry context across a sequence of model and tool calls. NVIDIA says some trajectories process as many as 3 million tokens. Retrieval-augmented generation (RAG) adds relevant enterprise information to a prompt, creating still more context to handle. During inference, model parameters and KV cache are both held primarily in HBM, putting pressure on the same scarce resource.
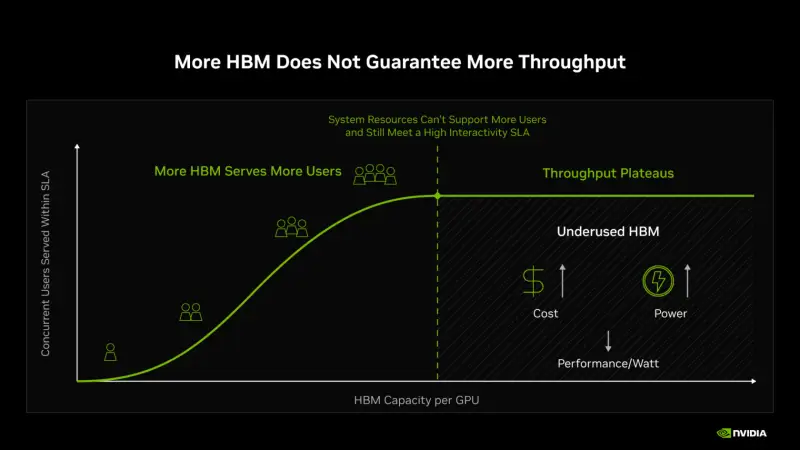
More HBM can accommodate a larger cache or more concurrent users, but capacity alone doesn’t determine performance. Users share memory bandwidth, which governs how quickly data moves between memory and compute. If that movement can’t keep pace with the GPU, added capacity may sit underused while still adding cost and power draw. Engineers call this limit the memory wall.
Three ways to put HBM to work
NVIDIA’s response targets three kinds of memory demand: model weights, inactive KV cache and RAG indexes. The company combines changes to data formats with systems that distribute or relocate data.
Reduce and distribute model weights. NVIDIA’s NVFP4 format takes less space for weights than FP8, which the company describes as the lowest precision available on its Hopper platform. Several model builders have released NVFP4 checkpoints, including FLUX.2 [klein] from Black Forest Labs, Inkling from Thinking Machines Lab, Beam 1.0 from Reflection, Meta Muse Spark, Step 5 Preview and NVIDIA Nemotron 3.5 Super VL. The listed examples point to adoption of four-bit weights for inference, though the source provides no quality comparison for these models.
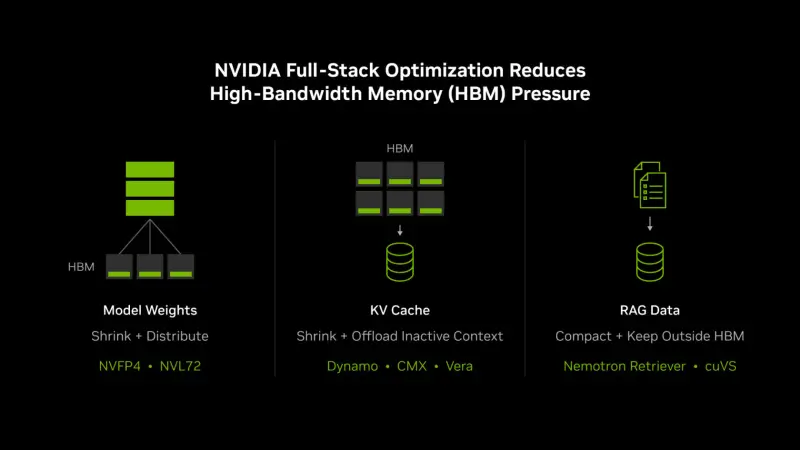
Within an NVL72 system, weights can also be distributed across as many as 72 GPUs. Each GPU then holds a smaller share, freeing some of its HBM for cache and additional concurrent requests.
Compress and move KV cache. Applying NVFP4 to KV cache reduces its footprint compared with FP8, allowing more context to remain in HBM. For context that is paused during a tool call, NVIDIA describes two further steps. The Vera CPU can shorten the inactive period by executing tools faster; its large LPDDR memory, connected to Rubin GPUs through NVLink-C2C, can also hold paused context nearby.
When context isn’t active, NVIDIA Dynamo can move it to NVIDIA CMX context memory storage, then return it before it’s needed again. CMX is designed for more capacity at much lower cost per bit than HBM. It is shared across servers, unlike local SSDs, and is designed without the long-term data protection overhead used for persistent enterprise data—an approach suited to short-lived context. NVIDIA names Cloudian, DDN, Dell Technologies, Everpure, HPE, IBM, NetApp, VAST and WEKA among CMX storage partners.
Dynamo’s KV Cache Reuse function coordinates cache across GPU memory, CPU memory and storage, so context computed once can be reused elsewhere in the system. That can reduce repeated work as requests move through the hierarchy.
Keep RAG indexes out of HBM. RAG systems represent documents as embeddings and organize them in a searchable index. NVIDIA says its Nemotron Retriever models produce smaller embeddings with higher retrieval accuracy, while its cuVS library supports building and serving the index across CPU memory and storage. The index can remain outside HBM; only retrieved passages need to enter the model’s context.
Reported throughput gains
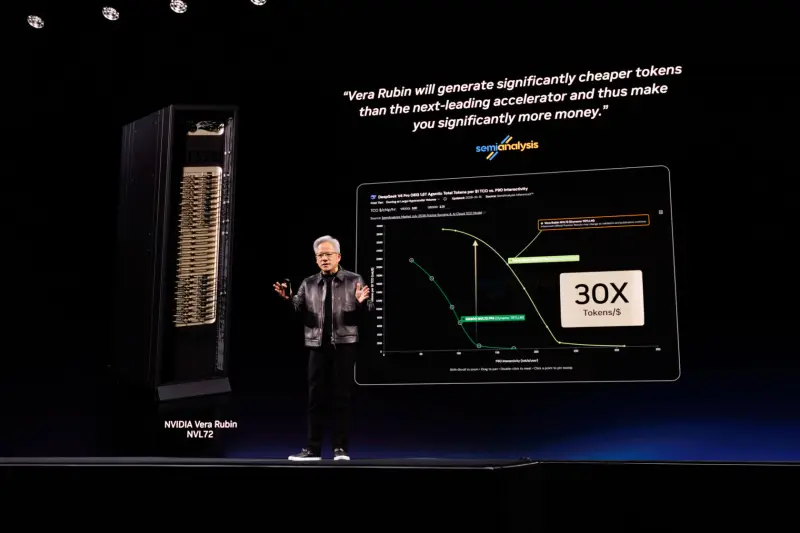
On the SemiAnalysis AgentX DeepSeek V4 Pro workload, NVIDIA reports that GB300 NVL72 delivers up to 10× the throughput per dollar of its H200 platform at 100 tokens per second per user. HBM capacity per GPU roughly doubles in that comparison. At 125 tokens per second per user, NVIDIA says Vera Rubin NVL72 delivers up to 30× the throughput per dollar of GB300 NVL72, with HBM capacity per GPU up about 3%.
These are workload-specific vendor-reported comparisons, not a guarantee of the same gains across models or serving setups. The figures also make response speed part of the comparison: the reported results specify a per-user token rate, alongside throughput per dollar.
For operators, the relevant measure is useful output within power and response-time limits. NVIDIA’s case is that compressing weights and cache, sharing context, and shifting inactive data to cheaper tiers can increase the work each byte of HBM supports. Whether that translates to a particular deployment depends on its workload and memory traffic; the key figure to watch is how much throughput the full system delivers at its required response speed.


