How LangChain Built a Paid Media Agent for Cross-Channel Analysis and Campaign Changes
- Cargo
- Machine Learning
- Shipped
- Shipper
- Christopher Williams
- Readers
- 950
LangChain’s agent combines ad data, warehouse metrics and human review, cutting reporting time and helping paid media drive 20% of marketing pipeline.
LangChain’s paid media agent helped the company expand advertising across five channels while giving a small marketing team a way to analyze results, prepare reports and propose campaign changes. In six months, paid media went from contributing none of the company’s marketing pipeline to 20%. From June to August, cost per qualified lead fell 30% as monthly spend rose about 60%; on LinkedIn, the largest social channel, it was 40% below January’s level.
Those results came with a practical engineering lesson: an agent’s performance depends on the work environment and data rules around the model. LangChain equipped its agent with a sandbox, business documentation, task specific tools and code for repeatable calculations. The model handled interpretation and recommendations, while people reviewed proposed changes before they were applied.
The system also reduced the cost and runtime of an early reporting workflow. After moving calculations into code and removing unnecessary model calls, LangChain reported that the workflow became about 40 times cheaper and 13 times faster, with runtime falling from 18 minutes to 85 seconds. The team also saved about $5,000 per month by bringing analysis and reporting in house rather than relying on an agency.
From organic growth to five paid channels
For its first three years, LangChain’s sales pipeline grew largely through open source, content, YouTube, community activity and meetups. In January, the company decided to add paid advertising to reach prospects beyond those organic channels, including people in new regions and enterprise decision makers. The plan was to grow from an organic growth engine to five paid channels in six months.
That expansion created a workload the small marketing team could not easily manage by hand. It had to track new campaigns, creative and targeting experiments, and an increasing volume of performance data. Each ad platform organized its data differently. Campaign settings and advertising metrics also did not map neatly to downstream outcomes such as signups, sales inquiries and content downloads. As product releases and campaign volume increased, it became harder to tell what was running, what was working and what to test next.
LangChain set out to build an agent that could follow product announcements, draft campaigns, suggest keywords, test variations and bring experiments to the team for review. The longer term idea was a recurring learning cycle: inspect results, propose a change, observe what happened, record the lesson and use it to inform future work.
A weekly analyst in Slack
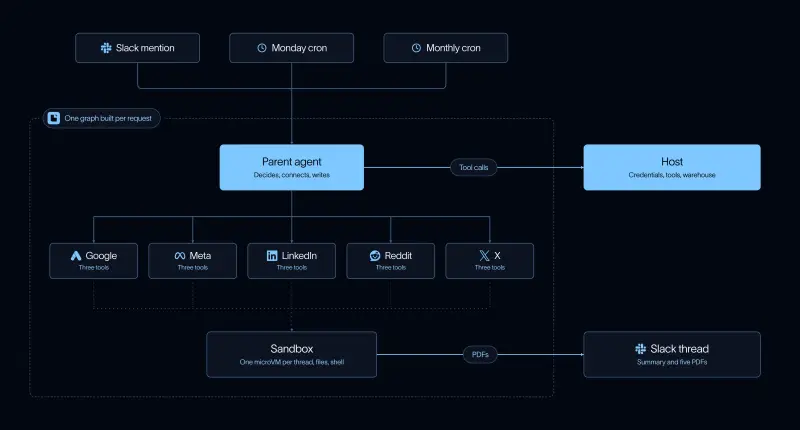
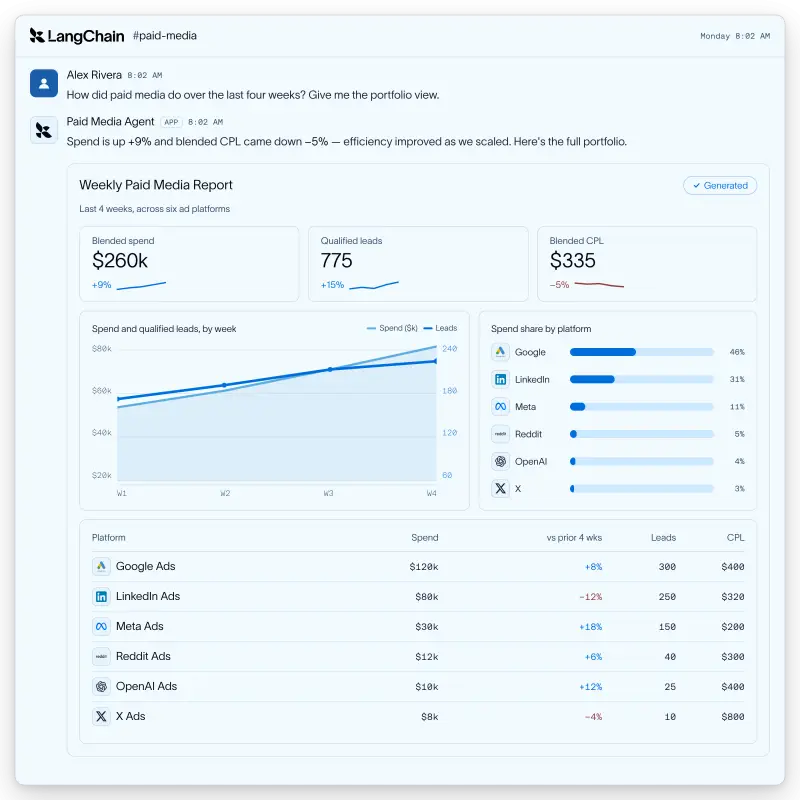
The agent runs on a schedule and responds to questions in Slack. Each Monday, it combines advertising platform data with lead and pipeline information from the company’s warehouse. It posts a summary and a branded PDF for each platform, describing what changed, why the change may have occurred and what the team could do next.
People can ask follow up questions in the Slack thread, including questions about campaign performance, costs and pipeline. The agent can also suggest new keywords, targeting adjustments, ad copy and search campaigns using the team’s playbook and encoded decision rules. When a recommendation involves changing an account, it can prepare a proposal for review rather than applying the change on its own.
Give the agent a working environment
LangChain approached the system as a new paid media analyst. The agent needed a computer to work in, software for analysis and reporting, access to relevant data, and documentation about how the business makes decisions. That framing shaped the agent’s runtime and the structure of its knowledge.
The runtime and sandbox
LangChain used Deep Agents as the agent harness. It provides core features for file access, code execution and working memory, along with tools for planning, assigning work to subagents and managing context as tasks grow. The paid media specific tools, instructions and company knowledge sit on top of that foundation.
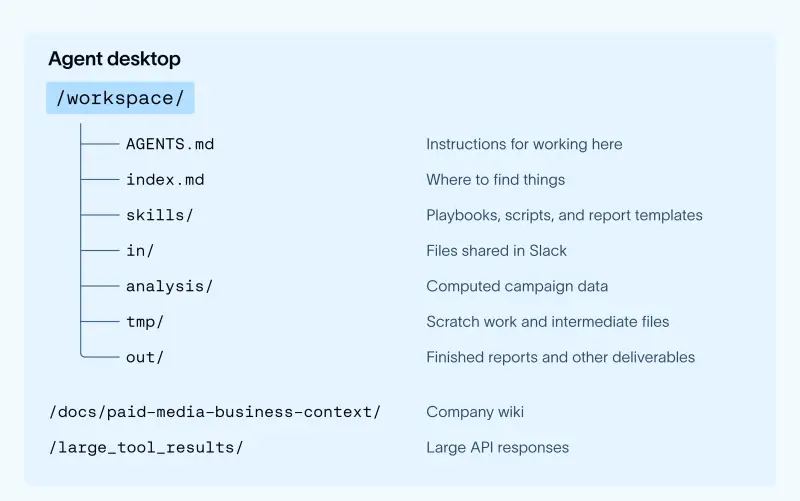
Each run gets a LangSmith Sandbox, an isolated microVM with a 32 GB disk and a shell for running commands. The sandbox gives the agent a place to handle files and execute code without affecting other runs or the underlying system. Its installed software includes pandas and DuckDB for analysis, openpyxl for spreadsheets, and WeasyPrint and Jinja2 for report generation.
Business knowledge and working data are stored as Markdown in six skills and a 19 page wiki. LangChain baked the software and wiki into a saved sandbox image, or snapshot, so each new run starts from a prepared environment. The snapshot reduced average startup time by 10 seconds.
Different tasks call for different workstations. LangChain’s content generation agent uses a setup with a headless browser, ffmpeg, media tools and a brand book. A finance agent might need spreadsheet support and heavier data processing. The job determines what belongs in the environment.
Context as a map
The agent also needs to know what its role is, how the company works, which methods to use and what rules apply. Putting all of that into one system prompt would make the prompt long, expensive to include in every run and difficult to keep current. LangChain instead treats the prompt as a guide to information stored elsewhere.
This design reflects a common source of agent failures: the model may lack the needed information, or relevant details may be crowded out by material that does not apply to the task. The team organized knowledge so the agent could load what it needed when it needed it, rather than carrying the full business context in every request.
The system separates context into five layers:
- System prompt: A short description of the agent’s role, instructions for operating, rules about where numbers come from and guidance for presenting results. It points to the playbook, wiki and index rather than duplicating their contents.
- Skills: Six folders containing instructions that are revealed progressively. At first, the agent sees each skill’s title and description, then it can load the instructions that fit the task.
- Wiki: Nineteen pages of company specific knowledge, including how the funnel works, what each campaign is meant to achieve, which system owns each metric and why the team made particular decisions.
- Live tools: Tools fetch frequently changing information such as spend, account settings and pipeline when the agent needs it. The system has 218 such calls, so making them discoverable on demand helps avoid loading irrelevant details into context.
- Deterministic code: Code handles calculations, date windows, account matching and fixed safeguards. One safeguard prevents the agent from cutting a top pipeline driver based on a single poor week.
Skills describe reusable procedures: how to read data, calculate results, write a report, prepare a change and apply the performance playbook. The wiki holds information specific to LangChain, such as which campaign is intended to build awareness, which should produce demo requests, and what the team decided in July. A useful test is whether the instructions would work at another company: if they would, they belong in a skill; if they depend on LangChain’s business, they belong in the wiki.
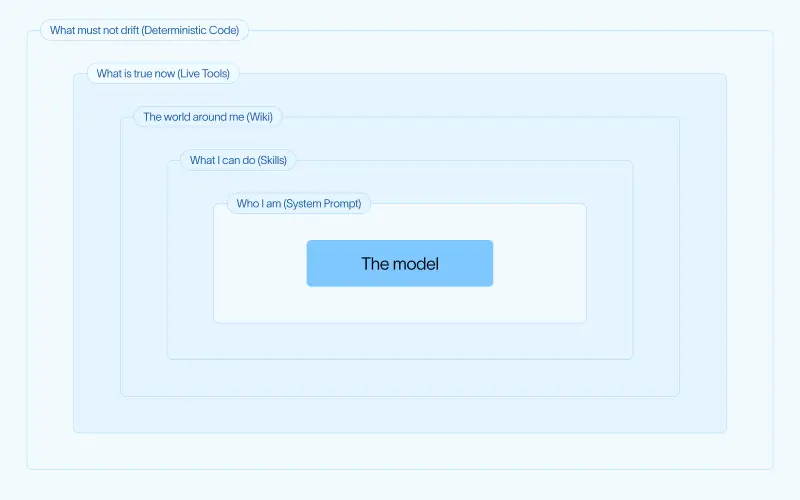
This separation draws on the idea of an LLM wiki and LangChain’s own work on Wiki Memory. It also means new questions can sometimes be answered by combining information and software already available in the workspace, even when nobody has built a dedicated workflow for that exact question.
One runtime for scheduled reports and Slack
The first design used two separate agent graphs because the experiences had different requirements. The scheduled reporting graph used a Deep Agent, a sandbox, a larger model and PDF generation. Slack needed faster replies, so it used a lighter loop with a cheaper model, advertising and warehouse tools, and read only access.
That split lasted five weeks. Each new capability had to be built twice, and the two interfaces fell out of sync. Slack could not handle attachments because it lacked a sandbox, while questions about a Monday report could not be answered in the thread because the report came from a different graph.
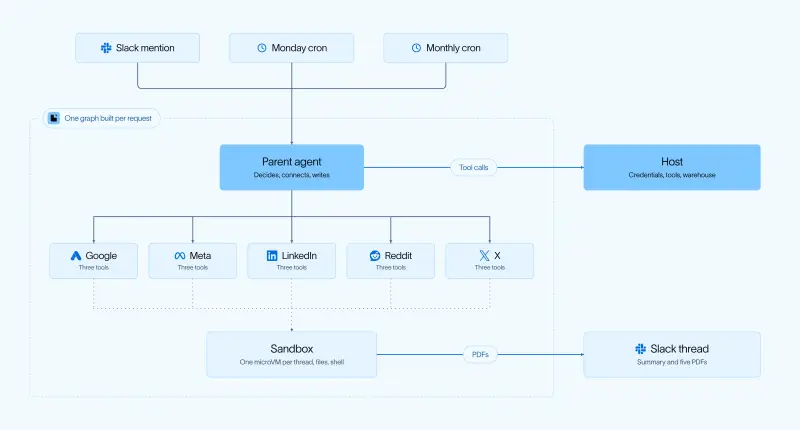
LangChain concluded that scheduled reports and Slack were two ways to reach the same analysis, not separate products. The team moved to one graph, instantiated fresh for each request, while giving each request only the state and capabilities it needs. Each thread gets its own sandbox and checkpoint. Scheduled runs and Slack mentions enter with different run modes: the scheduled flow receives a single task tool that delegates to one subagent per platform, while Slack receives a wider set of read, warehouse and campaign operations tools.
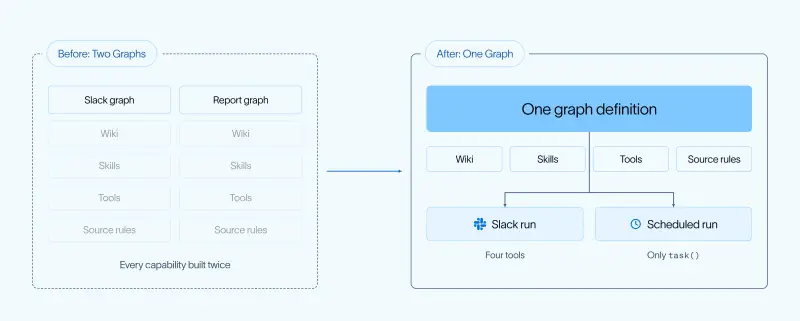
LangSmith Deployment hosts the shared runtime and handles scaling and scheduled runs. With the sandbox available in Slack too, the agent can open a report PDF and answer questions in the thread where that report was posted. The broader design lesson is to use one runtime with different capability profiles for different entry points. A shared foundation does not require every user or task to receive the same tools and permissions.
Keep calculations and metric rules out of model judgment
The first reporting version gave the model nearly all of the work. It received every campaign row, keyword, pipeline record and landing page check, then had to calculate spend and week over week changes, classify performance and write the report. The approach worked, but on a frozen test set a single report consumed about 3.9 million input tokens, took 1,112 seconds and cost just over $3. The model also had to recompute the underlying numbers on each run, making the output harder to verify.
LangChain shifted repeatable work into Python. Code now fetches data, aligns date windows, calculates totals and comparisons, applies fixed rules and writes a compact result set into the sandbox. The model interprets that evidence, considers likely causes, judges performance against campaign goals and recommends next steps. In the team’s tests, this split made the early reporting workflow about 40 times cheaper and 13 times faster, reducing runtime from 18 minutes to 85 seconds.
Choosing the correct source for each metric was another part of making results dependable. Six platforms had different identifiers, conversion definitions, attribution windows and campaign hierarchies. Rather than force all of that into one supposedly perfect schema, LangChain set a source of truth for each kind of information. Advertising platforms are authoritative for media activity such as spend, impressions and clicks. The warehouse is used for outcomes after conversion, including leads, opportunities and pipeline.
The distinction mattered in practice. Some Google video campaigns did not join cleanly into the warehouse because its campaign matching relied on keywords, which video campaigns may not have. About 10% of Google spend was therefore missing from the warehouse, despite Google having the correct spend figure. Meta could report that an ad produced a conversion, while the warehouse could better identify the type of conversion, such as a “Contact Sales” request or a “Sign Up.”
LangChain encoded these source rules in the wiki and removed tools that would let the agent query the wrong system for a metric. When records cannot be joined reliably, the agent preserves that limitation instead of filling gaps with guesses. Its answers include the relevant source, date window and attribution model so the team can see how a figure was produced.
Find tools when the question requires them
Questions about advertising spend and pipeline cross systems. Ad platforms hold spend and click data; the BigQuery warehouse connects campaign activity and website conversions with qualified leads, Salesforce opportunities and pipeline. LangChain wanted the agent to investigate across these systems without loading hundreds of tool definitions at the start or building a separate query tool for every possible question.
Pipeboard’s MCP exposes more than 200 advertising platform tools. In June, loading even a smaller, read only catalog of tool names, descriptions and arguments took 38,000 tokens before the agent had read the user’s question. Most of that information would be irrelevant to any one request.
The warehouse posed a related problem. LangChain had fixed queries for recurring questions, such as pipeline by campaign or conversions by ad group. A new grouping, such as pipeline by individual sales opportunity, would require another dedicated tool.
For advertising tools, the team put the catalog behind three operations: search for up to eight tools relevant to the question, read the full schema for a selected tool, and run that tool through a server. Campaign changes use a separate path that requires approval. For the warehouse, the agent can describe available tables and fields, then run an analytical query using the schema it has inspected.
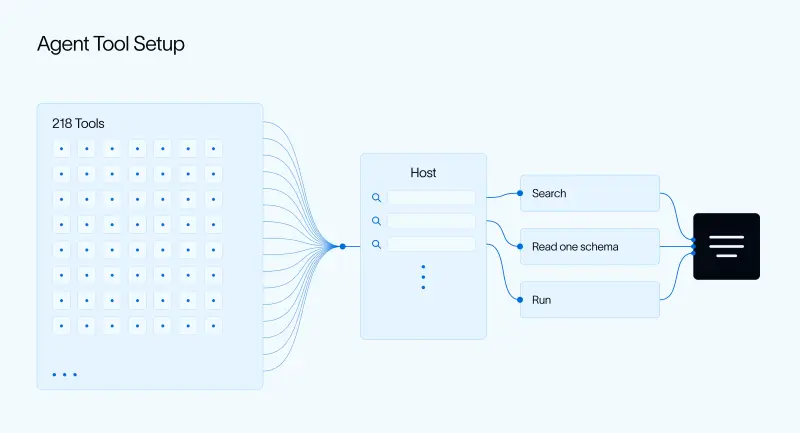
The catalog reduced the first turn to about 12,000 tokens. LangChain’s comparison found it was four times cheaper than loading every schema while maintaining the same judged quality. The catalog has since grown to nearly three times its earlier size while its context cost has stayed roughly consistent.
The team compared fixed warehouse tools, a query interface and both together across 60 live runs. Fixed tools handled routine questions, but appropriately reported deeper questions as unsupported. Both versions with the query interface answered all the analytical questions in the test. LangChain kept both: fixed tools provide a direct route for common requests, while the query interface covers questions the team did not anticipate.
Subagents need boundaries beyond separate context
Combining results from five advertising platforms raised a design question: should each platform run independently, should one agent handle all of them, or should a parent agent delegate to platform specific subagents? LangChain tested all three approaches on live data.
Independent runs were easiest to build, but each saw only one platform. The result was several Slack messages and weak cross channel synthesis. The consolidated approaches produced one combined output. LangChain chose a parent agent with one subagent per platform because the parent could keep its context small while each subagent handled platform specific data and caveats in its own context window.
Separate context windows did not prevent every form of interference. Initially, two subagents wrote reports to the same location and shared a completion flag. After the first one finished, the second could mistake the shared flag for its own and stop before producing a report. The fix was to give each platform its own report location and completion state.
Another subagent became stuck trying to confirm that its PDF had rendered. It repeatedly checked files, used a large number of tokens and eventually tried to build the PDF from scratch. LangChain narrowed the subagent’s tools to three: read context, compute and render. If rendering succeeds, the task is complete.
These failures show why a separate context window is only one part of isolation. Builders still need to specify which tools and files each subagent can access, what state it owns, what it must return and how the parent should handle a failure.
Turn recommendations into reviewed changes
An agent that only reports performance can amount to a more conversational dashboard. LangChain wanted the system to help the team act on its findings, so it can suggest changes in Slack, including adding keywords, adjusting geographic targeting and creating search campaigns.
Write access brings permission and review requirements. People outside paid media can ask about campaign performance and pipeline, but only designated team members can edit or approve proposed changes. The server checks Slack user IDs before accepting either action. A request from someone without the required access is blocked, leaving the proposal pending.
Proposals appear as Slack approval cards built with Block Kit. Authorized reviewers can compare current and proposed settings, edit the plan and approve the final version. Code then applies the approved change and checks the advertising platform to confirm it succeeded. The agent contributes analysis and a recommendation; a human decides whether the change proceeds.
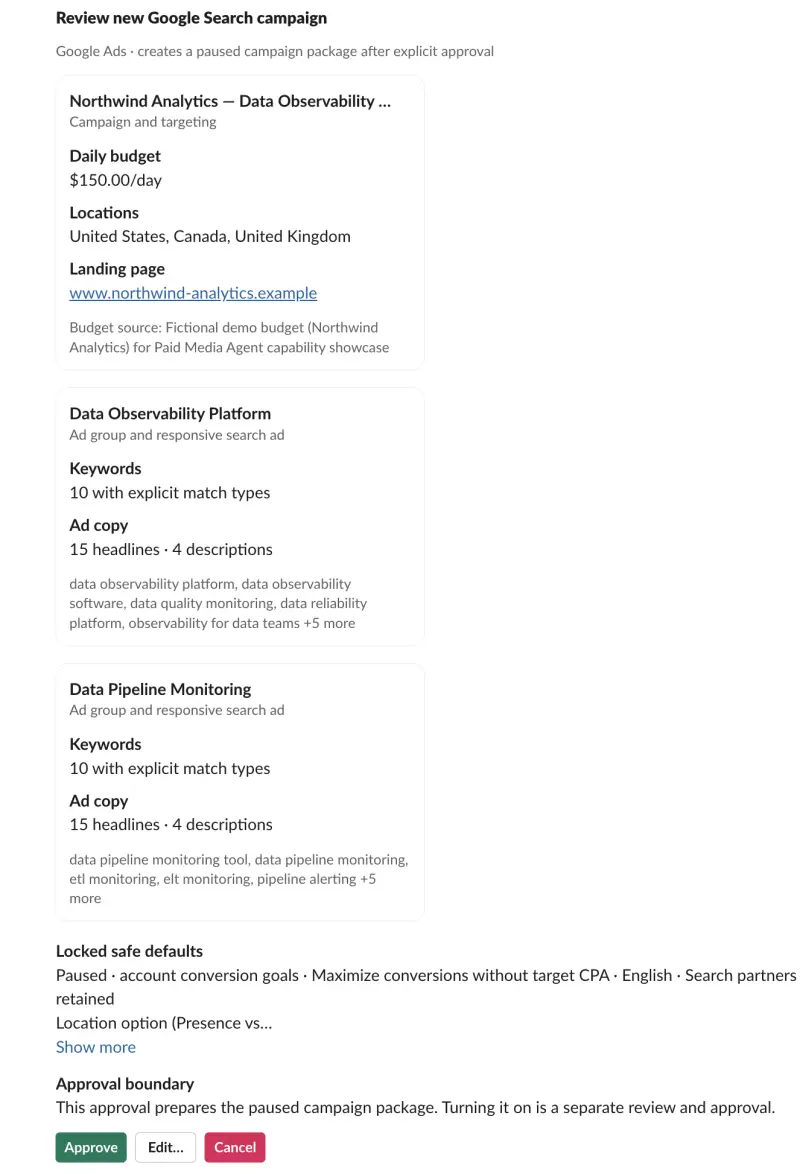
Slack is a useful first interface because the discussion, recommendation and approval can stay in one thread. It works best for focused decisions. Larger jobs, including campaigns with many ad groups and creatives, bulk edits or plans that take several rounds of revision, become difficult to manage in chat. LangChain is moving those workflows into a dedicated agent interface while retaining Slack for questions, recommendation reviews and approvals.
What the team would carry into another build
LangChain’s experience points to a set of practical design choices for agents that need to investigate unfamiliar questions, produce checkable results and support actions:
- Equip the agent for its actual job. Provide a sandbox, suitable libraries, the right data and useful documentation. A prepared workspace can help answer new questions without requiring a purpose built workflow for each one.
- Keep procedures separate from company knowledge. Skills describe how to do the work, the wiki captures business specifics and live tools provide current information. Separating these layers makes them easier to update without expanding the system prompt.
- Use code when results should be repeatable. Calculations, comparisons and fixed safeguards are easier to check when handled deterministically. That leaves the model to interpret evidence and explain what it may mean.
- Specify boundaries around delegated work. Subagents need clear tool access, file and state ownership, expected outputs and failure handling. A separate context window alone does not define those boundaries.
- Measure whether the agent completes useful work. Lower token use, cost and latency matter alongside answer quality and completion rate. Optimizing only for resource use can leave the system unable to finish the task.
- Use repeated failures to guide integration work. Questions the agent struggles with can reveal where data joins, metric definitions or dedicated tools need improvement.
From scheduled analysis to a shared learning loop
Today, the agent mainly responds to scheduled runs and requests from the team. LangChain wants it to monitor campaign performance more actively, flag changes that merit attention and propose experiments for people to review.
The next step is to connect what teams learn across the go to market process. Engagement with a campaign could help shape sales follow up. Pipeline movement, sales conversations and deal outcomes could in turn clarify which customers the company should reach and influence future campaign targeting and messaging.
That direction depends on shared knowledge as much as on more automation. LangChain wants its go to market agents to contribute to common playbooks, so that lessons gathered in one part of the funnel can inform decisions elsewhere. The paid media agent is a working example of how to build toward that goal: keep facts traceable, give the model focused context, and make the path from recommendation to action explicit.
The project is available as an open source paid media agent, including advertising tools, paid media skills, a sample wiki, reporting and approval workflows. LangChain also shared a recording of its agent walkthrough covering the design and code. The implementation can be adapted with a team’s own account connections and business context, then deployed to Slack using Managed Deep Agents.


